◆ RESOURCES · BLOG
Enterprise AI Is New. The Rules for Running Production Systems Aren't.
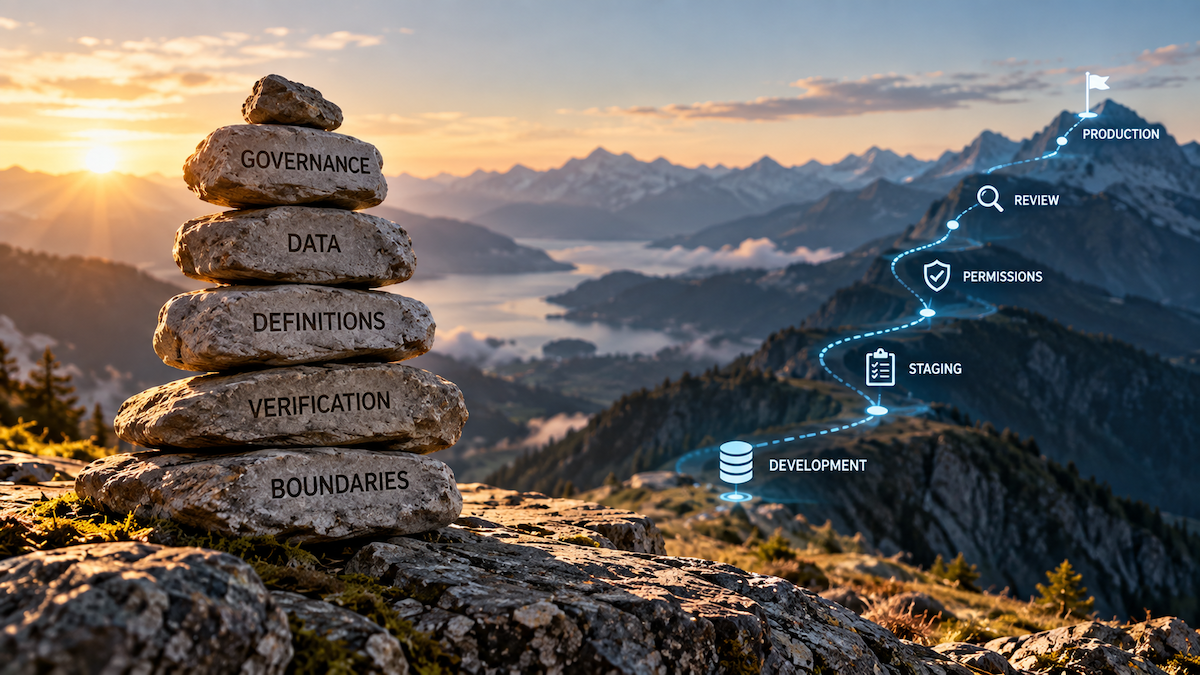
The technology worked. The architecture failed. Why Enterprise Analytics AI needs an operating layer before agents get permission to act.
The technology worked. The architecture failed.
One of the more interesting AI stories this year involved an AI coding agent deleting a production database. The agent was supposed to be working on a routine task in a staging environment. It ran into a credential problem, found an API token it could use, and made a decision that ultimately resulted in the deletion of production data. The story got a lot of attention because it sounded like exactly the kind of thing people have been warning about with AI agents. But the most important part of the story is not that the AI somehow broke into a system or bypassed security. It used credentials it was allowed to use, reached an API it was allowed to call, and performed an action the system was willing to perform. The technology worked. The architecture failed.
From advice to action
That distinction is going to become increasingly important as companies move from experimenting with AI to actually allowing AI to participate in running the business. For the last few years, most enterprise AI has been relatively safe because most of what we have asked it to do has been advisory. Summarize a document. Write an email. Generate some SQL. Analyze a spreadsheet. Explain why revenue changed. If the answer is wrong, a person usually sees it before anything significant happens. Agents change that equation because we are starting to give AI the ability to do things. Update Salesforce. Modify an order. Open a support ticket. Change a forecast. Send a customer an email. Execute code. Call an API. Update a database. There is a very big difference between an AI system that tells you what it thinks should happen and one that has permission to make it happen.
I do not think this is an argument against AI agents. Quite the opposite. I think agents are going to become an important part of how businesses operate. But if we are going to give AI more authority, we need to become much more thoughtful about the architecture underneath it.
MCP is new. Distributed systems aren't.
That is also why I have been interested in the debate around MCP, or Model Context Protocol. Julien Simon has argued that MCP risks ignoring lessons enterprise software learned over decades of building distributed systems. MCP solves a real problem by giving AI applications a standard way to discover and interact with tools, systems, and data. That is useful, and I expect we are going to see tremendous adoption around it. But MCP is new. Distributed systems are not. Authentication is not new. Authorization is not new. Data governance is not new. Least-privilege access, audit trails, versioning, rollback, and the separation of production from development are not new. We have spent decades learning painful lessons about how software systems should interact with one another. We should not suddenly forget those lessons because the thing making the API call can speak English.
In fact, I would argue that we need to be more careful with AI than we are with traditional software. Traditional software generally executes logic somebody explicitly programmed. AI interprets intent. If I write software that says delete customer 123, there is a very specific instruction somewhere in the code that caused that action. If I tell an AI agent, "Figure out why this customer is not syncing and fix it," I do not necessarily know what sequence of actions the model will decide constitutes "fix it." That is a powerful capability, but it is also exactly why Enterprise AI needs an operating layer between the model and the systems that actually run the company.
Enterprise AI needs an operating layer
I do not think the right architecture is simply an LLM connected directly to Salesforce, NetSuite, Snowflake, HubSpot, your support system, a dozen databases, and whatever other software happens to exist inside the company. That may make for an impressive demonstration, but it also creates an enormous number of ways for the AI to get confused. Most companies do not suffer from a lack of data. They suffer from having too many versions of it - the same analytics technical debt that AI is about to expose. Customer information lives in the CRM. Revenue lives in the ERP. Product activity lives somewhere else. Marketing has its own systems. Support has another view of the customer. Finance has spreadsheets. Operations has spreadsheets. Somebody usually has one very important spreadsheet that nobody else is allowed to touch. If Salesforce says an opportunity is worth $500,000 and finance says the contract is worth $420,000, which number should the model believe? If five systems contain five slightly different versions of the same customer, which one is real? Those are not AI questions. They are data architecture questions.
Trusted context and agreed meaning
Enterprise AI needs a trusted analytical layer where the business has already done the difficult work of connecting, cleaning, and reconciling its information. That does not mean replacing the systems that run the business. NetSuite should still be NetSuite. Salesforce should still be Salesforce. HubSpot should still be HubSpot. But the AI needs a governed place from which to understand how those systems relate to each other. Otherwise we are asking the model to rebuild the company's data architecture every time somebody asks a question. And even if all of the data is connected correctly, there is another problem that analytics teams already know very well: what do the words mean?
Ask five people in a company to define "customer" and you may get five different answers. Does somebody become a customer when they sign a contract, when they are invoiced, when they pay, or when they begin using the product? The same problem exists with revenue, pipeline, bookings, margin, active users, retention, and almost every other important business metric. We have struggled with this problem for years in dashboards and business intelligence systems. AI makes the problem more dangerous because language models are remarkably good at producing answers that sound authoritative. Someone asks, "What was our customer retention rate last quarter?" and the arithmetic may be trivial. The difficult part is understanding what the company means by "customer," what it means by "retention," and which calendar definition it uses for "quarter." Those definitions should not live inside a prompt. They should exist independently of the model. AI should reason from the meaning the business has already agreed upon, not invent that meaning as it goes.
Verification before irreversible action
Then we get to the issue that I think is going to become increasingly important: the difference between answering and acting. If AI notices that gross margin dropped unexpectedly last week, that is useful. Let it investigate. Let it pull together the relevant information. Let it explain what changed, show the calculation, and recommend what somebody should look at next. All of that can create tremendous value without exposing the company to much risk. Deleting data is different. Sending money is different. Changing a customer record is different. Communicating externally on behalf of the company is different. The closer an action gets to being difficult or impossible to reverse, the stronger the verification needs to become.
Before an AI system performs an important action, it should be able to establish where the information came from, how current it is, what definitions it used, and why it reached the conclusion it reached. And sometimes the correct answer should simply be that there is not enough verified information to proceed. I think this is one of the places where expectations around AI are slightly backwards. We tend to think an intelligent system should always produce an answer. In an enterprise environment, sometimes the most intelligent thing the system can do is refuse. "I do not know." "I cannot verify that." "The source data is stale." "These two systems disagree." "I need a person to approve this." Those are not weaknesses. Those are features of a system you can actually trust.
Detect what is missing
Enterprise AI also needs to understand something traditional analytics systems have often handled poorly: absence. Most monitoring systems are very good at detecting things that happen. A payment failed. An order arrived. Revenue crossed a threshold. A server generated an error. Some of the most expensive problems in a business involve something that did not happen. The order that never made it to fulfillment. The payment that should have arrived but did not. The customer whose data stopped flowing three days ago. The account that should have renewed but quietly disappeared from the process. If yesterday's data never arrived, the AI needs to know that today's answer may be incomplete. If a join unexpectedly eliminates a third of the customers, it should not confidently summarize the remaining two-thirds. Knowing what you do not know may turn out to be one of the most important capabilities in Enterprise AI.
Autonomy should be earned
All of this leads to what I think is the most important principle: autonomy should be earned. I do not think AI autonomy should be treated as an on/off switch. There is a natural progression. At first, let the AI gather information. Then let it analyze that information and make recommendations. Once it has demonstrated that it understands the workflow consistently, allow it to take narrowly defined actions. Create the ticket. Send the internal notification. Assign the follow-up. Update a controlled field. Over time, as confidence and evidence accumulate, some workflows may deserve more autonomy. Others may never deserve it, and that is fine. The goal is not maximum automation. The goal is useful automation. There should also always be ownership. When an AI system discovers a $2 million discrepancy in a forecast, somebody still needs to own what happens next. The last mile is not AI. The last mile is accountability.
More useful AI, not less
This is the architecture we have been thinking about as we build Sherpa AI. Not another chatbot sitting on top of a warehouse, and not an army of disconnected agents independently reaching into every system in the company. The goal is an operating layer for Enterprise Analytics AI: a place where the business can connect its information, agree on what that information means, understand where it came from, identify what is missing, and put boundaries around what AI is allowed to do.
I do not look at stories about AI agents deleting databases and conclude that companies should slow down their adoption of AI. I think the opportunity is far too large for that. But we have been building enterprise systems for a long time, and we have already learned that powerful systems need permissions, governance, observability, ownership, and limits. The lesson from the deleted database is not that AI made a stupid decision. Humans make stupid decisions too. The lesson is that the architecture allowed one bad decision to become an irreversible action. Enterprise AI may be new. That problem is not. And we already know how to solve it. Paying down analytics technical debt is part of that solution - because fluent models on ambiguous data are how confidence gets ahead of truth.
◆ YOUR NEXT STEP
Bring us the workflow you want to automate carefully.
We'll map trusted context, definitions, verification, absence detection, and the boundary between recommendation and irreversible action.
Start a working session ↗